Case Study — Efficient Fine-Tuning
Llama2 QLoRA Healthcare — Medical LLM on One GPU
A fine-tuned LLaMA-2-7B medical assistant trained with QLoRA on a single GPU — production-quality LLM fine-tuning without an expensive compute cluster.
The Challenge
Healthcare teams want fine-tuned LLMs but lack GPU budgets. Full fine-tuning of 7B-parameter models was impractical; teams needed a medical assistant trainable on commodity hardware like a Colab notebook.
What We Built
- QLoRA + LoRA fine-tuning of LLaMA-2-7B on a medical Q&A dataset
- 4-bit quantization cutting memory footprint by ~80% while preserving quality
- Single-GPU training pipeline runnable end-to-end on Colab
- Medical-assistant style chat outputs with helpful, grounded health responses
HuggingFacePyTorchQLoRALoRAPython
Results
Memory footprint reduction
~80% via 4-bit QLoRA
Training hardware
Single consumer GPU
Response quality
Comparable to full fine-tune
More Work
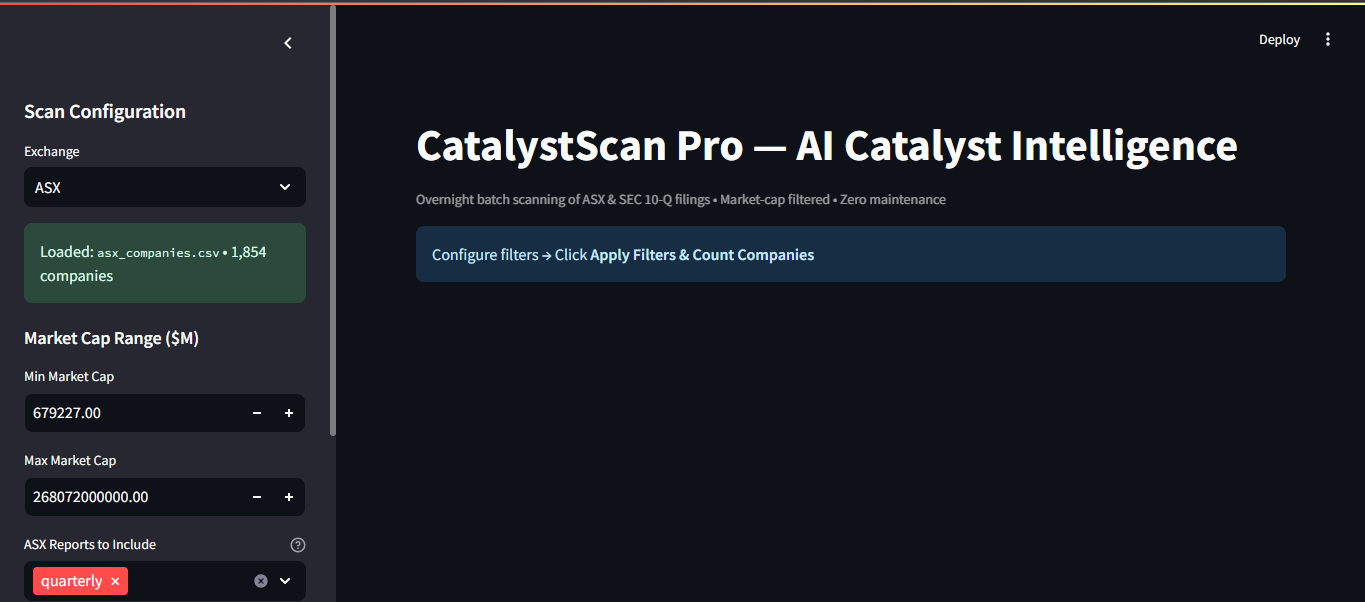
Batch Disclosure — Price-Moving Catalyst Detection
An AI-powered system that scans ASX and SEC filings for forward-looking disclosures — contracts, M&A, guidance — that move micro-cap prices before the market catches on.
WikiGen — Autonomous, Bias-Aware Knowledge Synthesis
A multi-agent GraphRAG system that autonomously writes reliable, bias-aware Wikipedia-style articles with verifiable provenance on every claim.
Let's Work Together
Build Something Like This?
This system solved a real problem. We can build something similar for you.